Performance
Protect AI interactions and agent actions without slowing enterprise workflows
Protect AI interactions and agent actions without slowing enterprise workflows
Runtime security must keep pace with interactive AI and autonomous agents. Serial inspections, repeated model calls, and distant processing can add delays that frustrate users or disrupt time-sensitive workflows. As applications scale, organizations need consistent policy decisions without making the protection layer a bottleneck.
PointGuard AI delivers the fastest enterprise guardrails and highly accurate controls through purpose-built detection and parallel policy evaluation. Prompt injection, safety, and sensitive-data checks run simultaneously in milliseconds rather than chaining their latency. Pre-execution controls evaluate agent actions before they reach tools or systems, while AI Gateway adds high-throughput model routing, failover, caching, and usage governance.
The result is near-real-time protection that virtually eliminates inspection delays while scaling across enterprise AI workloads.
guardrails
Use optimized, task-specific detectors to inspect prompts, responses, and tool outputs without sending every decision through a general-purpose LLM review loop. Purpose-built analysis supports accurate threat detection while keeping runtime enforcement responsive for chatbots, applications, and agent workflows under production load.
Evaluate prompt injection threats in milliseconds
Inspect safety and sensitive-data risks quickly
Keep interactive enterprise AI experiences responsive
parallelism
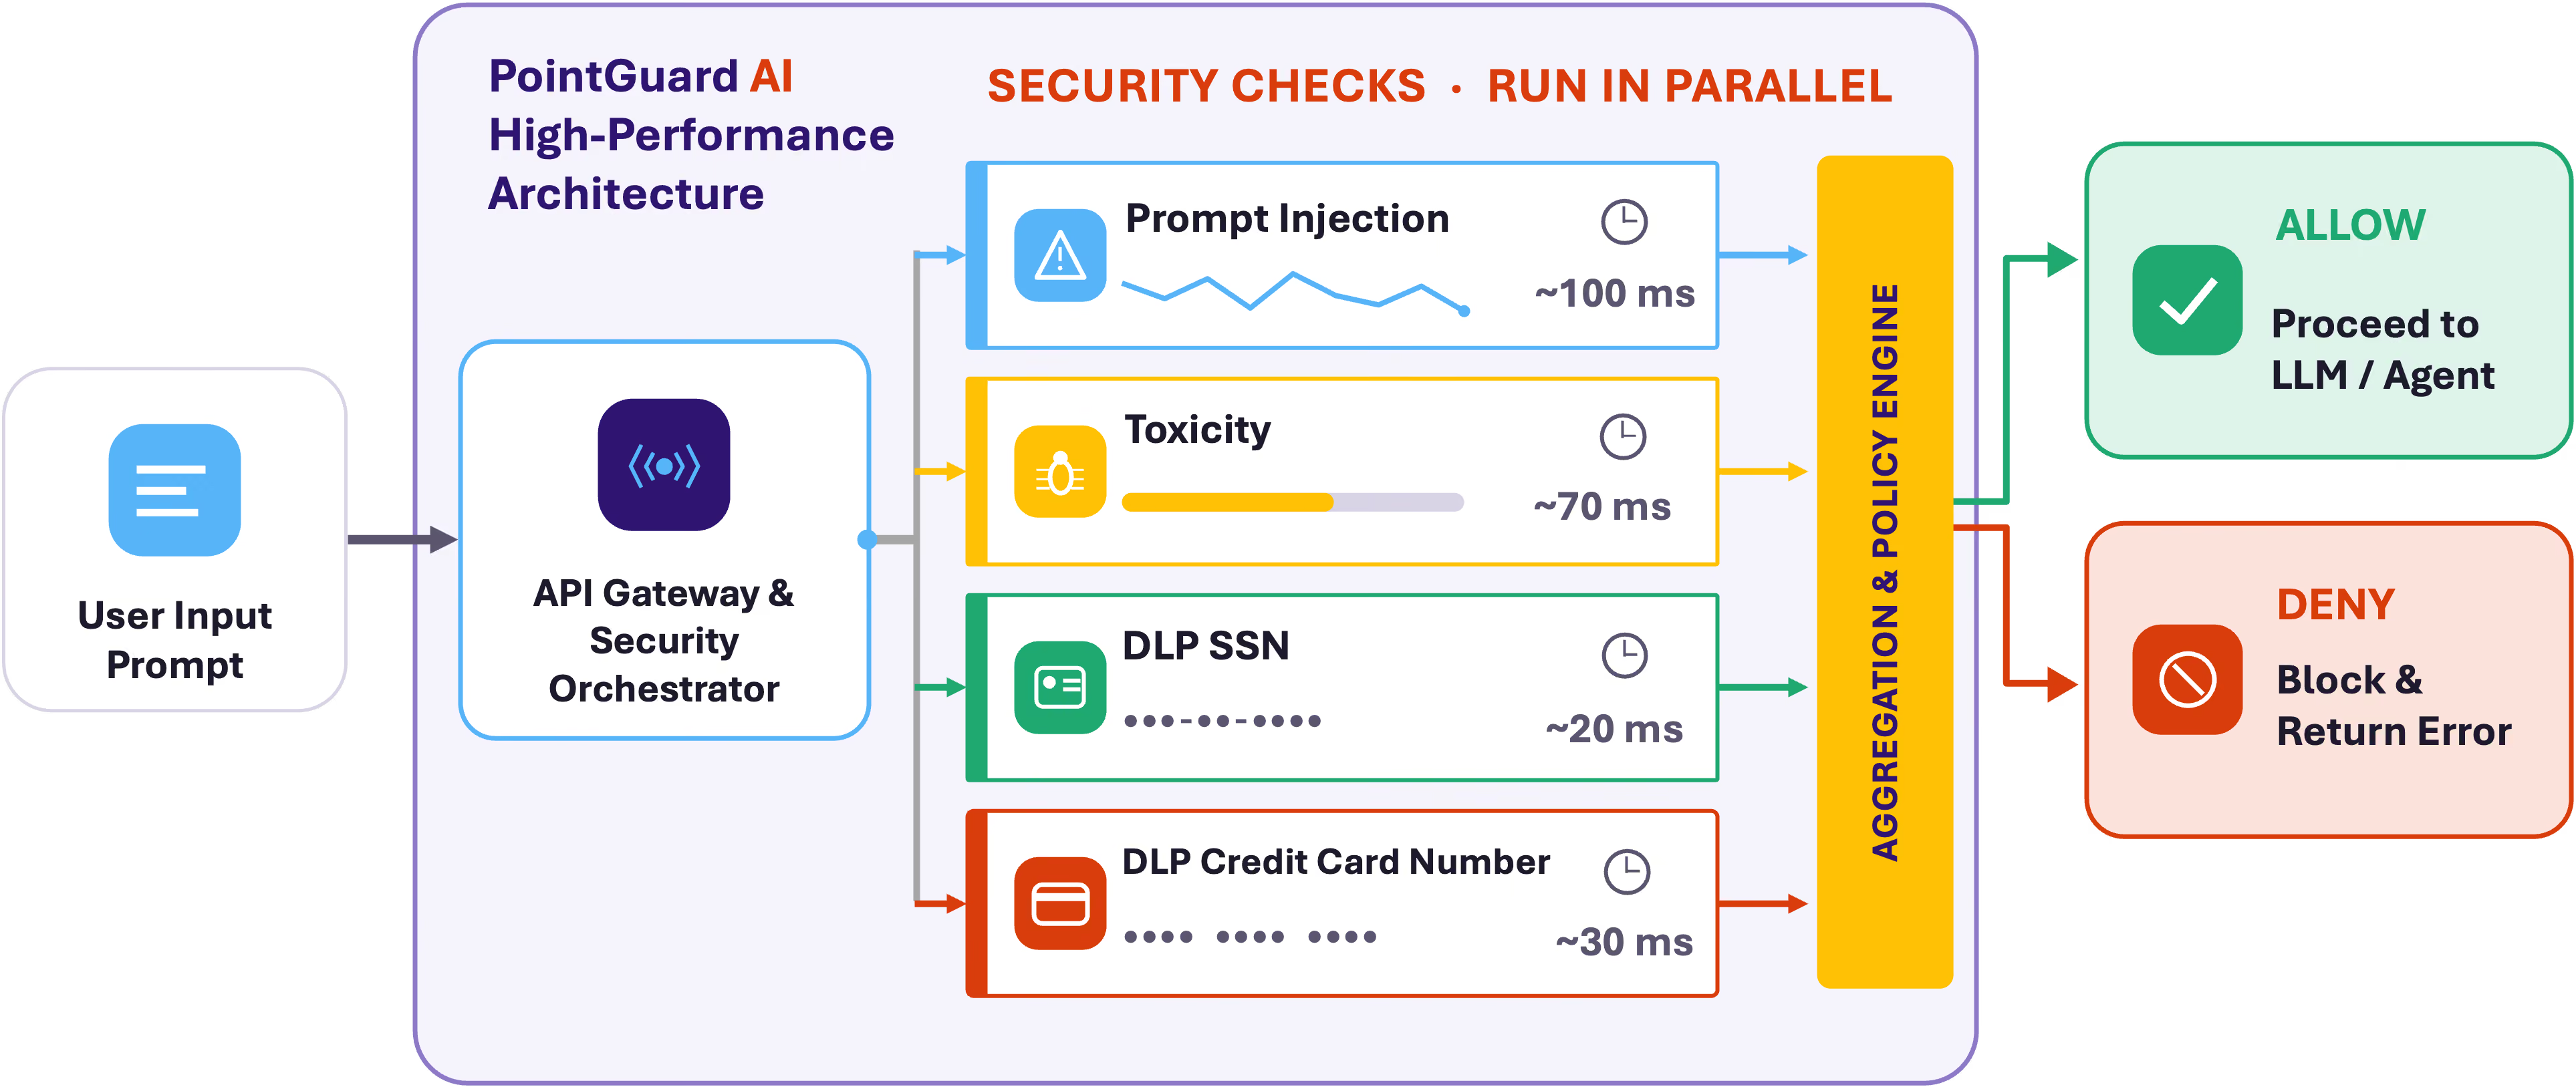
Evaluate enabled threat, safety, and DLP checks in parallel, then apply one aggregated policy decision. Processing time follows the slowest relevant check rather than the sum of every check. Teams can enforce multiple policies in the same interaction without creating a serial inspection queue.
Execute threat and safety checks concurrently
Run multiple DLP expressions in parallel
Avoid cumulative delays from sequential scanning
caching
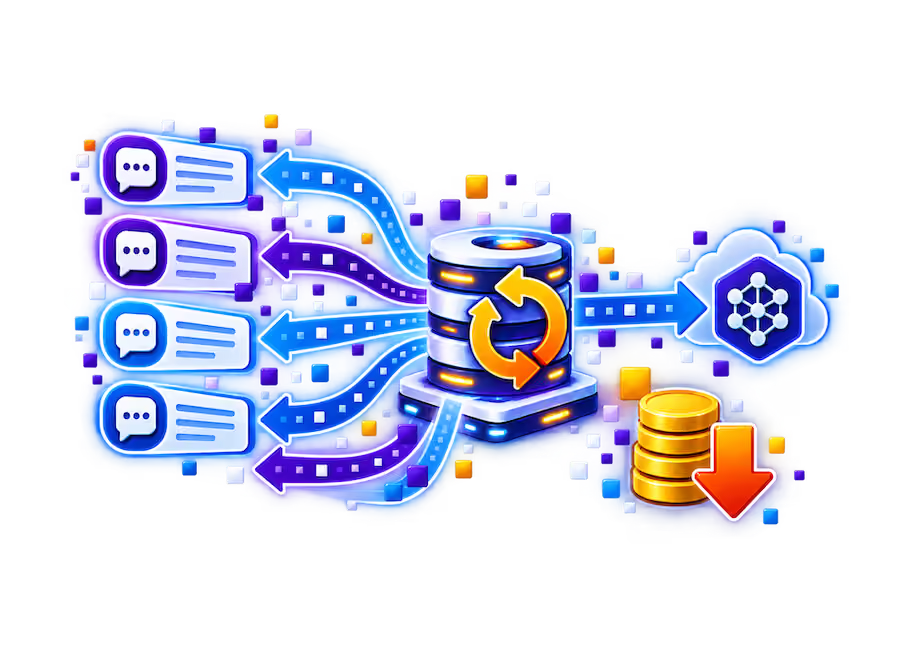
Cache frequently reused prompts, system instructions, and shared context so repeated interactions do not require another full upstream model request. Semantic prompt caching reduces redundant traffic, token consumption, and model-processing costs while improving response speed for high-volume AI applications and agent workflows.
Cache commonly reused prompts and shared context
Reduce redundant model traffic and token consumption
Lower costs while accelerating repeated interactions
accuracy
Combine specialized detectors with policy context, including application criticality, data sensitivity, and business requirements. Teams can tune thresholds and actions to reduce unnecessary disruption while blocking or redacting material threats. This supports precise decisions across different AI uses without treating every interaction as equally risky.
Tune decisions to application and data
Reduce unnecessary blocks through policy context
Select proportional actions for detected risks
gateway
AI Gateway uses a high-throughput runtime to route requests across SaaS, open-source, and in-house models with minimal gateway overhead. Automatic failover preserves service during provider disruption, while semantic caching can serve repeated requests without another upstream model call. Native telemetry helps teams monitor latency, errors, and spending.
Route high-volume AI traffic across providers
Fail over during upstream service disruptions
Reduce repeated calls with semantic caching
scale
Place inspection and enforcement near applications and sensitive data through supported SaaS, customer-hosted, and hybrid patterns. Batch complete interactions where appropriate, distribute controls across managed environments, and retain centralized visibility. The platform is designed to preserve response time as AI usage, policies, and agent activity grow.
Place enforcement near protected enterprise applications
Batch eligible interactions to reduce overhead
Scale security across distributed enterprise workloads
Clients Words
AppSOC brings it all together in one intuitive dashboard – helping me prioritize vulnerabilities and ensure compliance.
Customer Spotlight
Our expert team can assess your needs, show you a live demo, and recommend a solution that will save you time and money.
Find content, demos, case studies, guides, blogs, and more in our extensive library