

Inspect claims and policy chatbot inputs and outputs to block injected instructions and unsupported answers before policyholders see them.
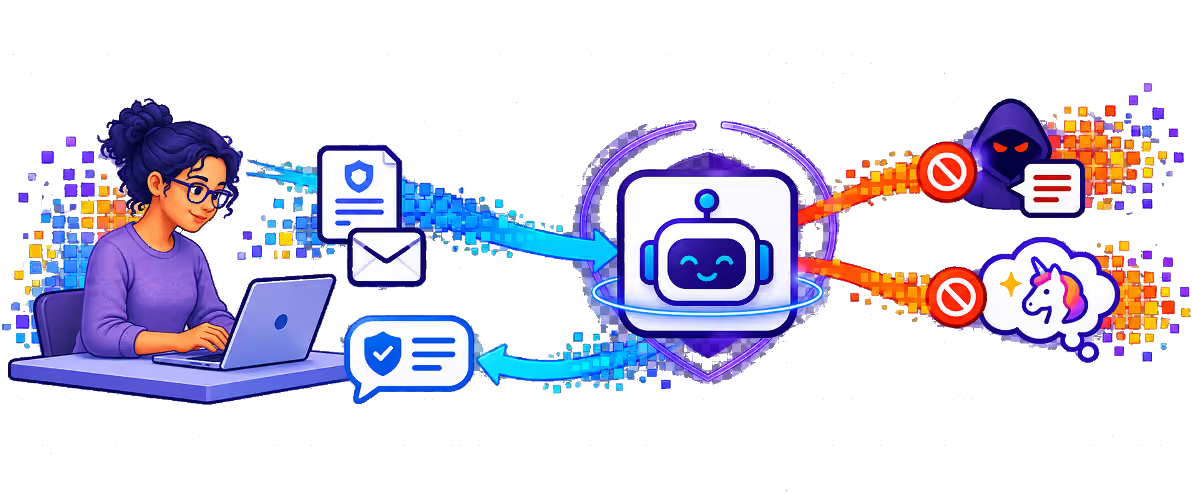
Customer-facing claims and policy chatbots retrieve documents, emails, and tool outputs to answer questions about coverage and claim status. That content can hide injected instructions, and models can produce confident answers about coverage that are simply wrong. PointGuard AI inspects inputs and outputs in real time, helping carriers block manipulation and unsafe responses before they reach policyholders.
Chatbots that sound authoritative can mislead policyholders or be steered by content they retrieve.
Runtime Guardrails and AI Red Teaming test chatbot behavior and enforce carrier-defined content policies at runtime.
1. Inspect inputs. Scan prompts, retrieved documents, and tool outputs for injection attempts using fine-tuned detection models at sub-100 ms latency.
2. Enforce response policies. Check generated answers against carrier rules for coverage statements, claim guidance, and restricted topics. Block or escalate responses that violate policy.
3. Test before release. Probe chatbots with coverage, claims, and adversarial scenarios. Review failures before approving a model or prompt change for production.
4. Monitor and retest. Track detections and violations over time. Retest after model, prompt, or knowledge-base changes to catch new failure patterns.
These controls reduce exposure to unsafe content; accurate coverage answers still depend on approved, current policy data.