

Run automated adversarial testing whenever underwriting and pricing models, prompts, or tools change.
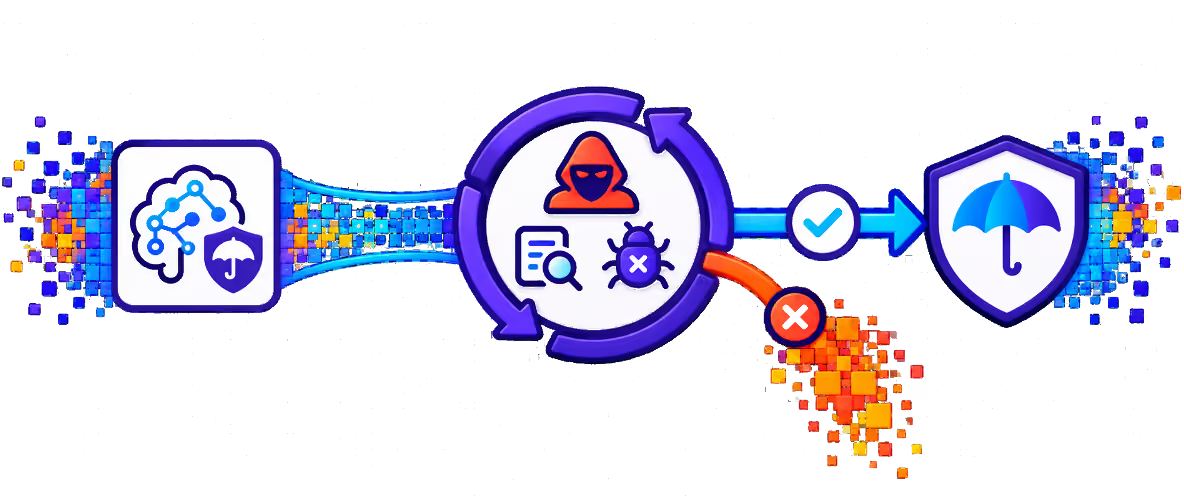
Underwriting and pricing models change with every release, and new manipulation techniques appear weekly. A red-team review at launch says little about the model running in production months later. PointGuard AI automates adversarial testing and reruns it whenever models, prompts, or tools change, giving carriers current evidence about how their AI behaves.
One-time testing cannot keep pace with model updates and evolving attack techniques.
AI Red Teaming runs repeatable adversarial tests and ties results to the systems and versions they cover.
1. Define insurance scenarios. Build probe sets for underwriting, pricing, claims, and customer service tasks, including security, harmful-output, and bias scenarios.
2. Automate testing. Run tests on a schedule and trigger them automatically when a model, prompt, or tool changes. Cover agents as well as models.
3. Review findings. Inspect exact prompts, responses, and failure rationales. Compare results across versions to spot regressions.
4. Feed remediation and governance. Route failures to owners and track fixes. Map results to OWASP and MITRE ATLAS for governance reporting.